To download the HTML of a website, use your browser's built-in "Save Page As" feature to store the full page source locally, or copy the rendered source from developer tools.
How to download the html of a website with 'Save Page As'
The "Save Page As" function is the quickest and most common way to grab a page's HTML because it requires no technical knowledge and works with any site. It saves the current page's markup directly to your hard drive, giving you a file you can open offline or inspect in a text editor.
- Open the website you want to save in your browser.
- Right-click anywhere on the page (or press Ctrl+S on Windows/Linux, or Cmd+S on Mac).
- Choose "Save Page As" from the context menu.
- In the dialog that appears, pick a folder and type a filename.
- Click Save.
In Firefox, the same steps apply: press Ctrl+S (Cmd+S on Mac) or use the menu button, then pick "Web Page, complete" or "Web Page, HTML only." Safari on Mac uses File > Save As, offering "Web Archive" (bundles all assets) or "Page Source" (only the HTML code). This method is ideal for a quick snapshot, but note that external resources like images or scripts referenced by the page may not be included unless you choose the "complete" option.
Copy the HTML source code with developer tools
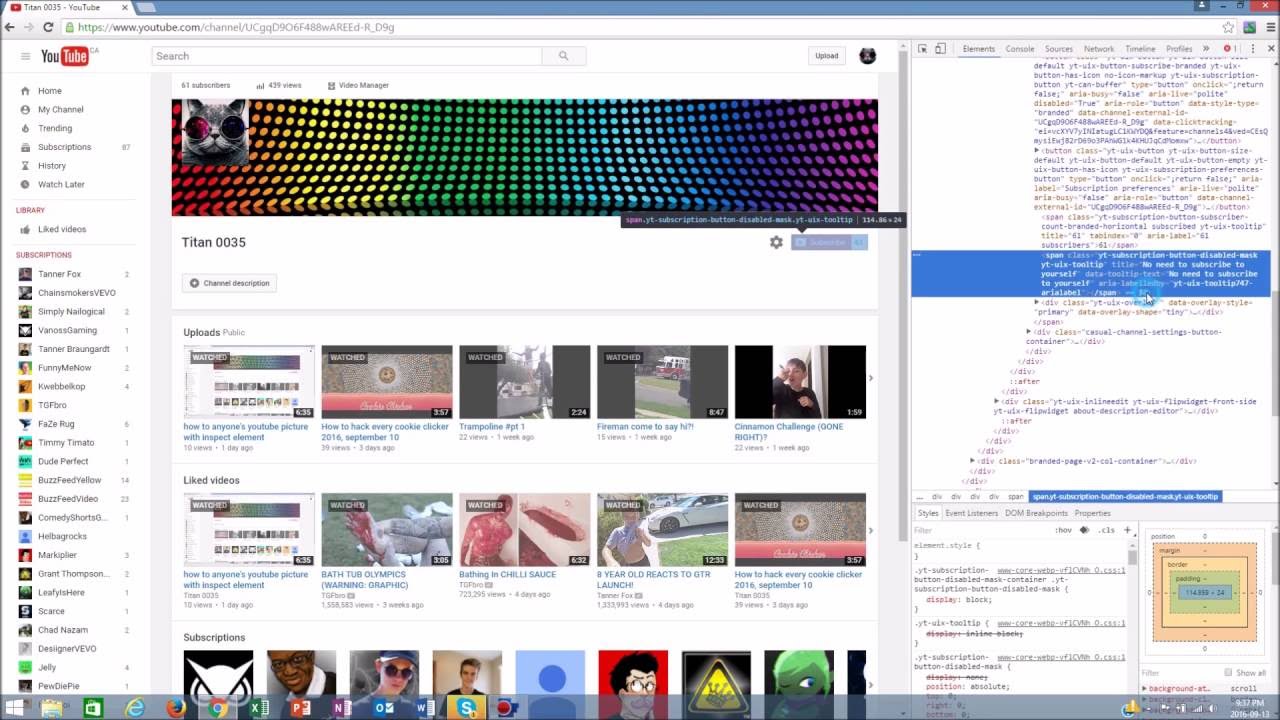
When you need the exact, fully rendered HTML, including changes made by JavaScript, developer tools give you direct access to the live source. Open the panel by right-clicking the page and selecting "Inspect" or "Inspect Element," or press Ctrl+Shift+I (Windows/Linux) or Cmd+Option+I (Mac). Click the "Elements" or "Inspector" tab, then right-click the tag and choose "Copy" > "Copy outerHTML." Paste that into a text editor and save it with an .html extension.
This method captures the current state of the DOM, which is useful for debugging or analyzing dynamic content. However, any edits you make inside the developer tools are temporary, they vanish on page refresh unless you set up a workspace to save changes to local files. Also, copying outerHTML only grabs the source markup, not the linked CSS, images, or scripts, so it won't produce a fully self-contained offline page.
Download HTML from the command line
For a no-frills, scriptable approach, command-line tools fetch raw HTML directly. Use curl to save a single page: open your terminal and run curl -o output.html https://example.com, replacing the URL with your target. The -o flag names the output file. Alternatively, wget does the same with wget -O output.html https://example.com.
These tools are fast and easy to automate, but they only retrieve the HTML response, they won't execute JavaScript or pull in assets. For a power-user move, wget can recursively mirror an entire site with flags like --mirror --convert-links --page-requisites, which downloads all linked pages, fixes links for offline browsing, and fetches necessary resources. This turns a single command into a full site archive, though it can be heavy on bandwidth and storage.
What to do after you download the html
Once you have the HTML file, open it in any browser to view the page exactly as it was saved, or use a text editor like Notepad, VS Code, or Sublime Text to inspect the code. If you saved only the HTML, expect missing images or styles because those are separate files. Remember, the "Save Page As" and command-line methods give you the document, not the full experience, so choose based on whether you need just the code or a browsable snapshot.