Parallel computing big data processing works by breaking massive datasets and complex analytical tasks into smaller, independent chunks that are executed simultaneously across multiple processors or machines. This divide-and-conquer approach directly tackles the core bottleneck of big data, the sheer volume and speed of information, by transforming what would be a sequential, hours-long process into a parallel, minutes-long one, while also providing the scalability and fault tolerance that traditional systems lack.
How parallel computing solves big data processing challenges
At its core, parallel computing is the computational equivalent of an assembly line with hundreds of workers instead of one. Rather than having a single CPU grind through terabytes of data one record at a time, parallel computing orchestrates a coordinated effort where each processor handles a distinct slice of the workload. This mechanism is what makes modern big data platforms like Apache Hadoop and Spark viable. Hadoop, for instance, uses the Hadoop Distributed File System (HDFS) to split files into blocks across a cluster, and then MapReduce processes those blocks concurrently on different nodes. The result is a linear or near-linear reduction in processing time as more machines are added, which is the fundamental reason why organizations can derive insights from petabytes of data in seconds rather than days.
What is parallel computing?
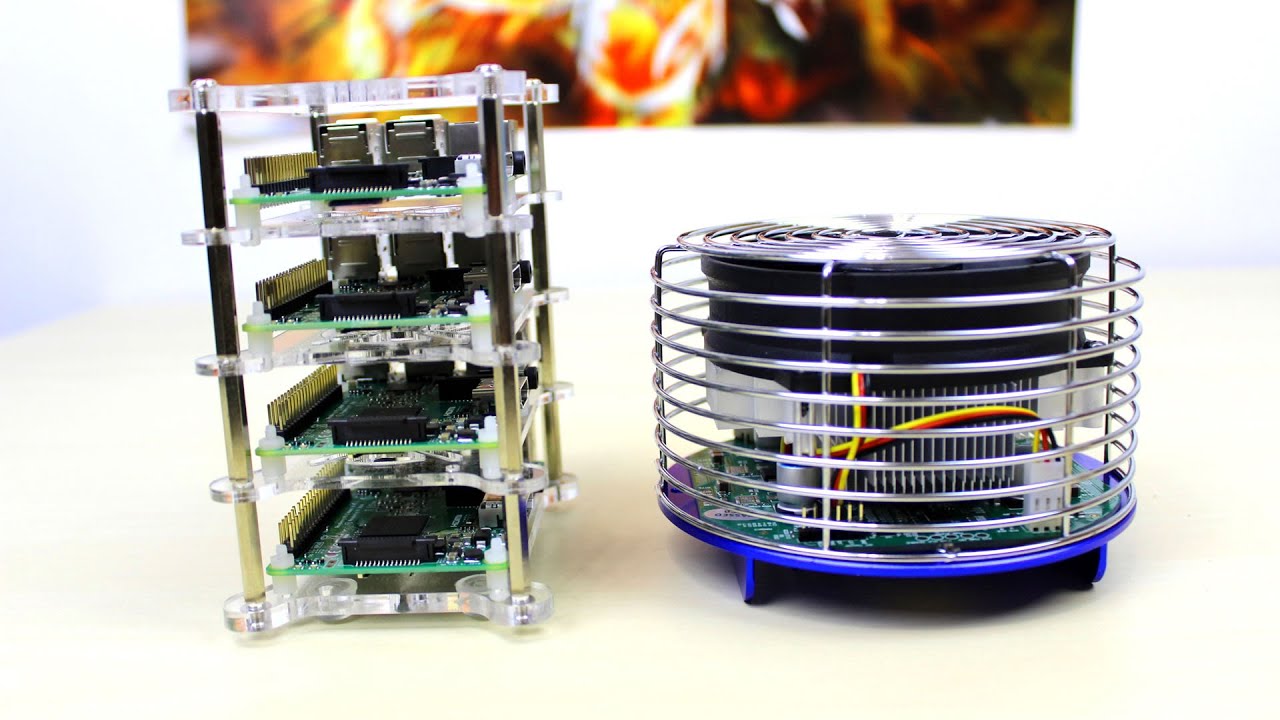
Parallel computing is a computational model where a large problem is decomposed into smaller sub-problems that are solved concurrently. Unlike serial computing, which executes instructions one after another, parallel computing leverages multiple processing elements, whether cores within a single CPU, GPUs, or entire servers in a cluster, to execute operations at the same time. There are two primary forms of parallelism used in big data processing: task parallelism and data parallelism.
Task parallelism divides a job into distinct functions or steps that can run simultaneously. For example, in a data pipeline, one processor might be cleaning raw data while another is running a machine learning model on a different subset, and a third is generating summary statistics, all at once. Data parallelism, on the other hand, splits the dataset itself into smaller partitions, with each processing unit applying the same operation to its own partition. This is the dominant pattern in big data frameworks: think of a query that scans a billion rows, with data parallelism, each node scans its own hundred million rows and then results are aggregated.
What is big data?
Big data refers to datasets that are so large, fast-moving, or complex that traditional data processing software cannot manage them effectively. The defining characteristics are captured by the "three Vs": volume, velocity, and variety. Volume means the sheer scale of data, terabytes or petabytes generated from sensors, transactions, logs, and social media. Velocity refers to the speed at which data streams in and must be processed, from real-time stock feeds to live clickstreams. Variety encompasses the different forms of data, structured tables, unstructured text, images, video, and JSON logs. A fourth V, veracity, is often added to highlight the noise, inconsistency, and errors inherent in such data. Together, these attributes create a processing problem that single-machine architectures simply cannot solve.
The core challenges of processing big data
Before parallel computing became standard, big data processing hit a wall of practical obstacles. The first is scalability: a single server has finite CPU, memory, and disk, so as data grows, processing time grows linearly or worse, leading to unacceptable delays. Data integration is a second hurdle, big data arrives from disparate sources (databases, APIs, log files) in incompatible formats, requiring complex ETL (extract, transform, load) processes that are themselves computationally heavy. Storage and management pose a third challenge: traditional relational databases struggle with the scale and schema flexibility needed, forcing organizations to adopt distributed storage like HDFS or NoSQL systems. Analysis speed is the fourth issue, running complex queries, aggregations, or machine learning algorithms on massive datasets with conventional tools can take hours or days, making real-time or even near-real-time decision-making impossible. Finally, data privacy and security become exponentially harder as data is copied across clusters and processed in multiple locations, requiring robust encryption and access controls that don't cripple performance.
Key benefits of parallel computing for big data
Parallel computing addresses each of these challenges head-on, offering four interlocking advantages that make it the indispensable backbone of modern big data infrastructure.
Parallelizability for speed and efficiency
The most immediate benefit is raw speed. Because big data processing tasks are inherently parallelizable, scanning, filtering, aggregating, and transforming can all be split into independent operations, parallel computing turns a sequential bottleneck into a concurrent workflow. This speed is not just a convenience; it enables real-time analytics, where organizations can react to customer behavior, system anomalies, or market shifts as they happen. Efficiency also improves because idle CPU cycles are eliminated; every processor is continuously engaged on its assigned slice of data, maximizing resource utilization.
Horizontal scalability
Parallel computing's second major benefit is horizontal scalability, the ability to add more machines to a cluster to handle more data or faster processing. This is a direct response to the volume challenge of big data. Instead of upgrading to a more powerful (and expensive) single server, organizations can simply add commodity hardware. Frameworks like Hadoop and Spark are designed to distribute data and computation across hundreds or thousands of nodes, and as data grows, more nodes can be added without rewriting the application logic. This elasticity also extends to the entire data pipeline, ingestion, storage, transformation, and analysis, so that no single stage becomes a bottleneck. The practical result is that processing time remains roughly constant even as data volume doubles, because the cluster size can scale in tandem.
Built-in fault tolerance
When processing petabytes of data across hundreds of machines, hardware failures are not an exception, they are a statistical certainty. A single server crash, network partition, or disk error could wipe out hours of computation if the system were not designed for resilience. Parallel computing frameworks address this with built-in fault tolerance. In Hadoop, for example, data is replicated across multiple nodes (typically three copies), so if one node fails, another has the data. MapReduce also provides task redundancy, if a task running on one node fails, it is automatically re-executed on a healthy node. This means that the overall computation continues without interruption, and the user does not need to manually restart the job. Fault tolerance ensures that big data processing is not only fast but also reliable, which is essential for production systems where downtime is unacceptable.
Data integration and analysis
Parallel computing also solves the data integration problem. Because diverse datasets, structured, semi-structured, and unstructured, can be distributed across a cluster, the integration process itself can be parallelized. Each node can process and clean its own portion of the data, converting different formats into a unified schema, and then the results are merged. This parallel ETL dramatically reduces the time required to prepare data for analysis. Furthermore, complex analytical operations, machine learning algorithms, statistical computations, graph traversals, are themselves parallelizable. Frameworks like Spark's MLlib and GraphX distribute these computations across the cluster, allowing organizations to run sophisticated models on massive datasets that would be impossible on a single machine. The result is that parallel computing not only moves data faster but also enables deeper, more complex analysis.
Real-world impact
The practical applications of parallel computing in big data are everywhere. Internet search engines like Google and Bing index billions of web pages using parallel processing across massive clusters, returning relevant results in milliseconds. In genomics, parallel computing processes DNA sequencing data, which can be hundreds of gigabytes per genome, to identify mutations and accelerate drug discovery. Financial institutions use parallel computing to run risk models and high-frequency trading algorithms on real-time market data, where every millisecond matters. Logistics companies optimize delivery routes by analyzing traffic, weather, and package data in parallel, reducing fuel costs and delivery times. Social media platforms analyze billions of posts and interactions to detect trends, personalize content, and target advertisements. In every case, parallel computing is the enabling technology that turns raw, unwieldy big data into actionable intelligence.
In summary, parallel computing is not just an optional enhancement for big data, it is the fundamental requirement. By dividing tasks and data across multiple processors, it delivers the speed, scalability, fault tolerance, and analytical power that organizations need to extract value from the ever-growing torrent of information. Without parallel computing, the promise of big data would remain an unfulfilled aspiration, limited by the physical constraints of single-machine computing.